The Frontier, as Seen in SF: GPUs, Video Generation, Niche Models, Robotics
Notes from San Francisco, late September through early October 2026.
GPUs and inference
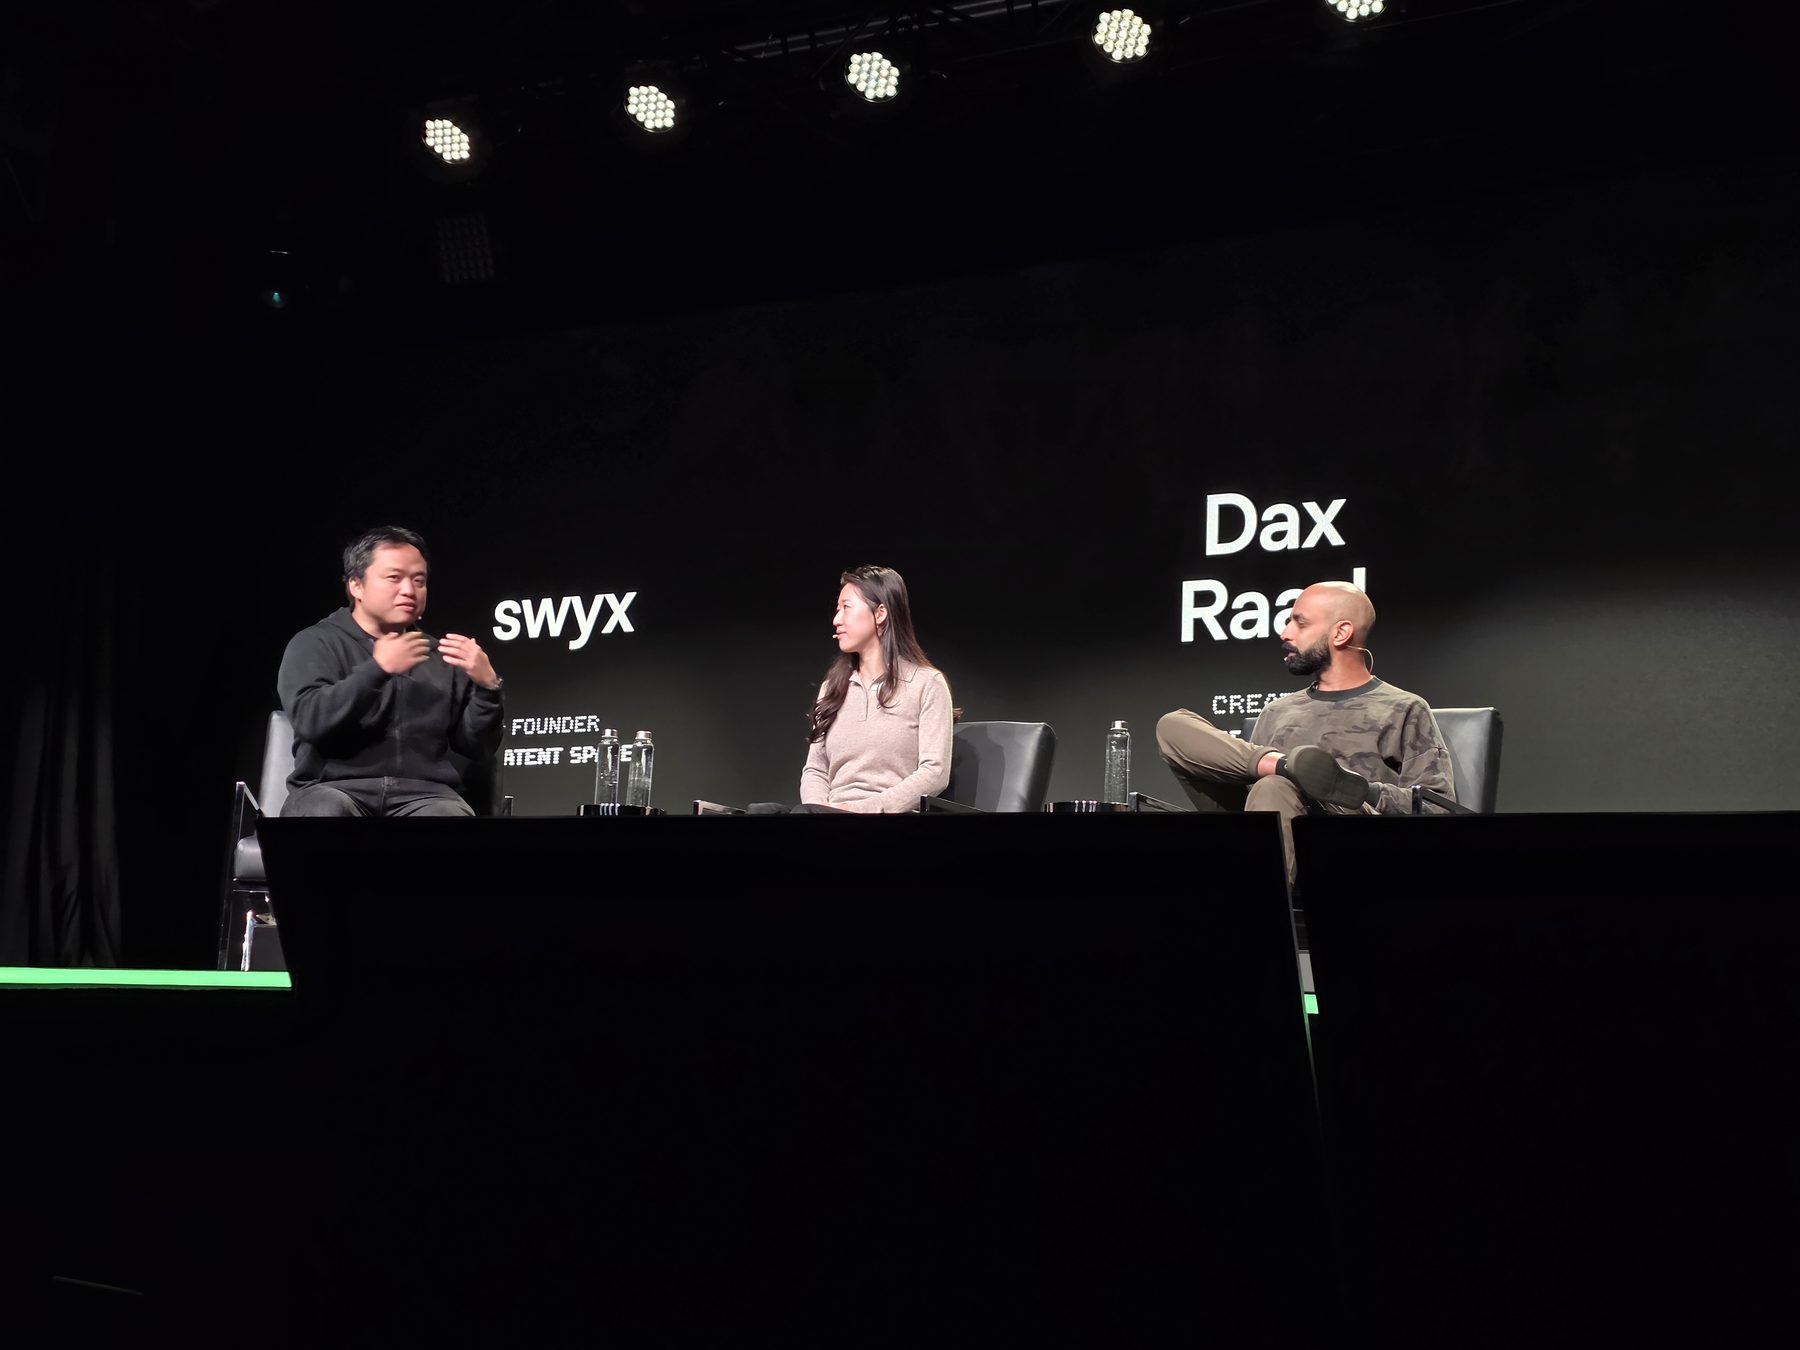
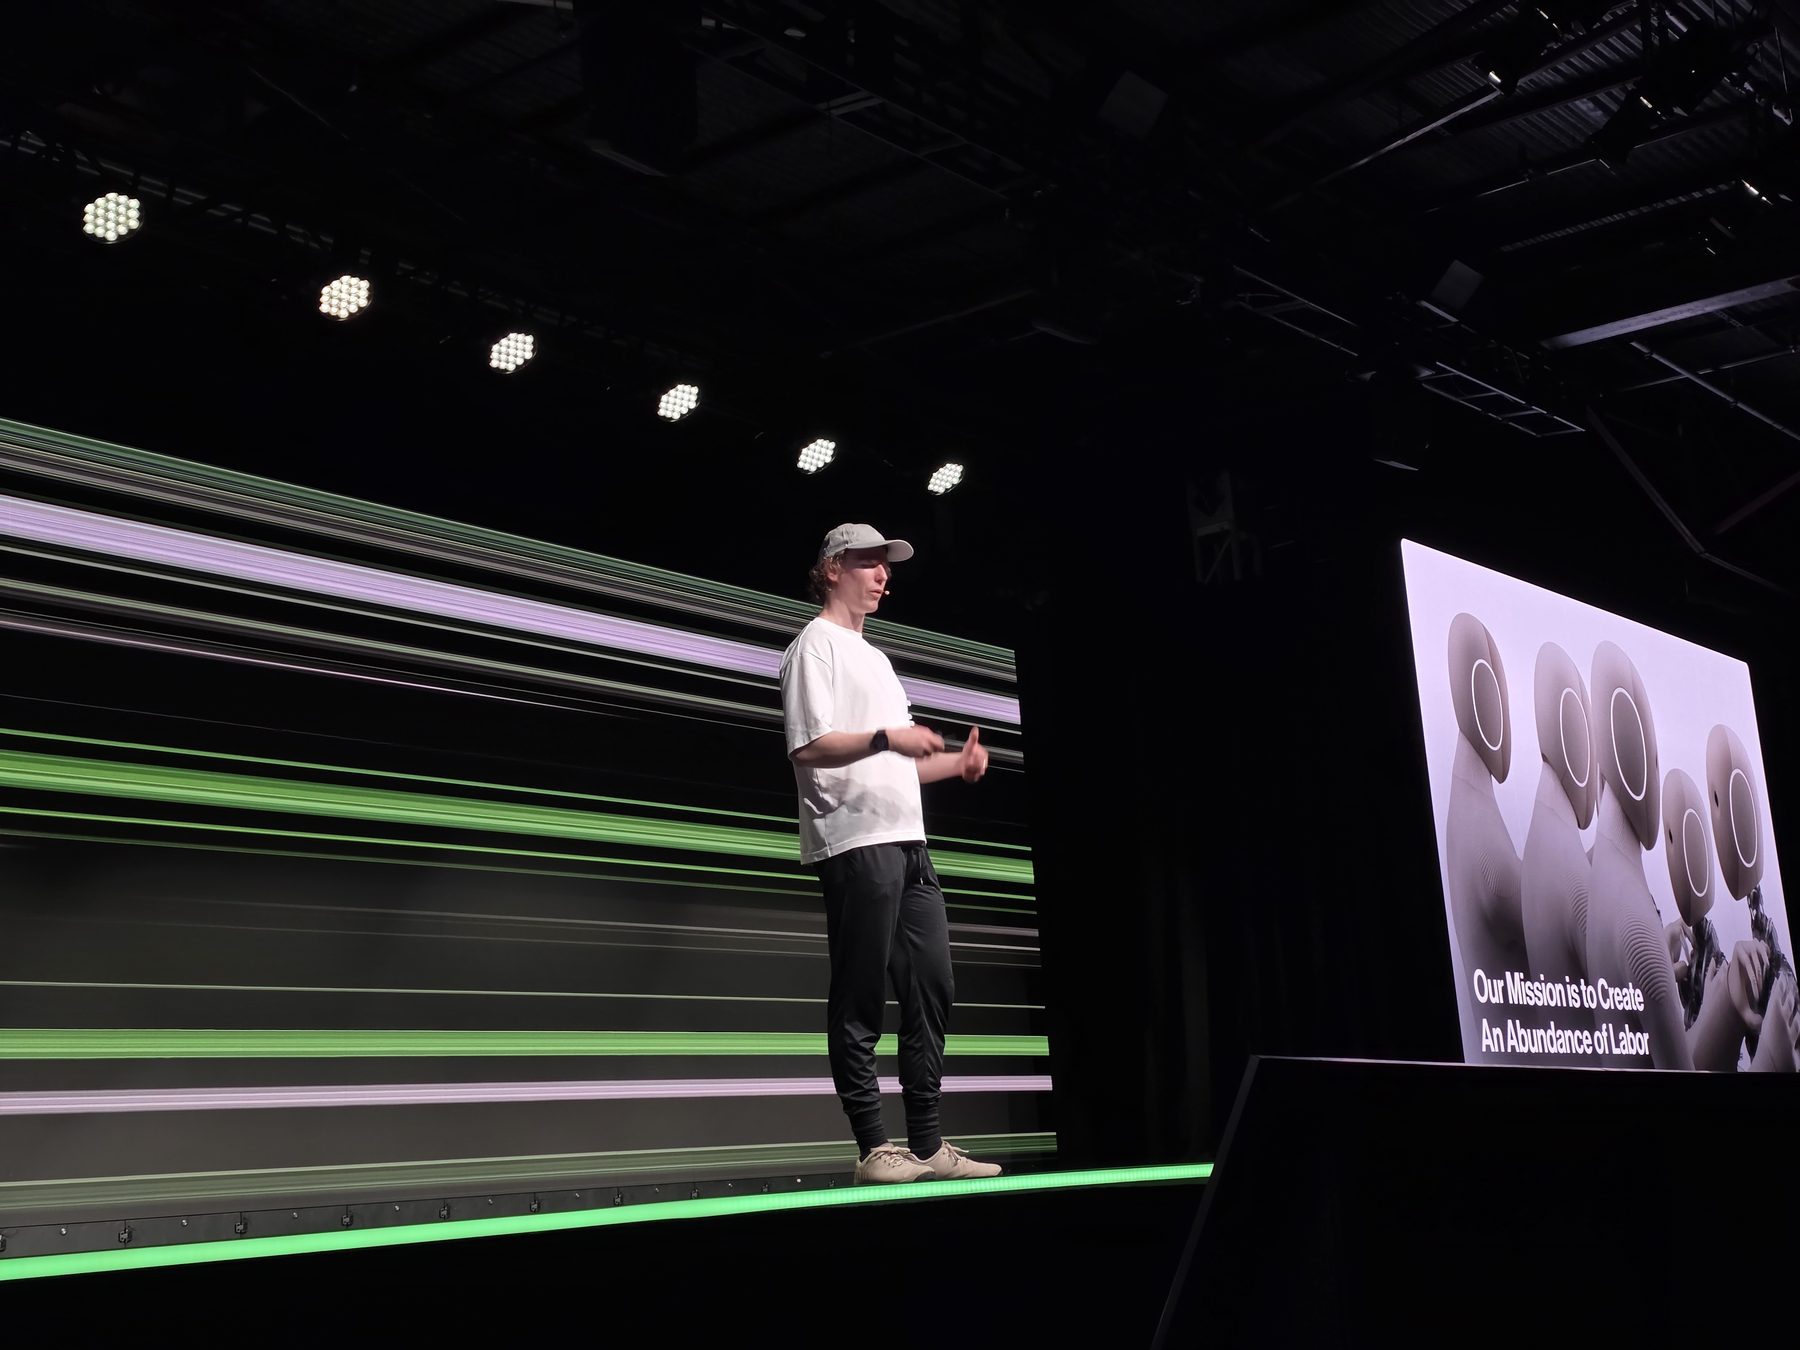
Runtime is Modal’s conference. swyx, Cat Wu, and Dax spoke, and the same day’s robotics session included Generalist, Physical Intelligence, and 1X.
Dreamscale Labs (YC F26) serves robot models from the cloud. Latency comes first, so they were looking for GPUs inside SF.
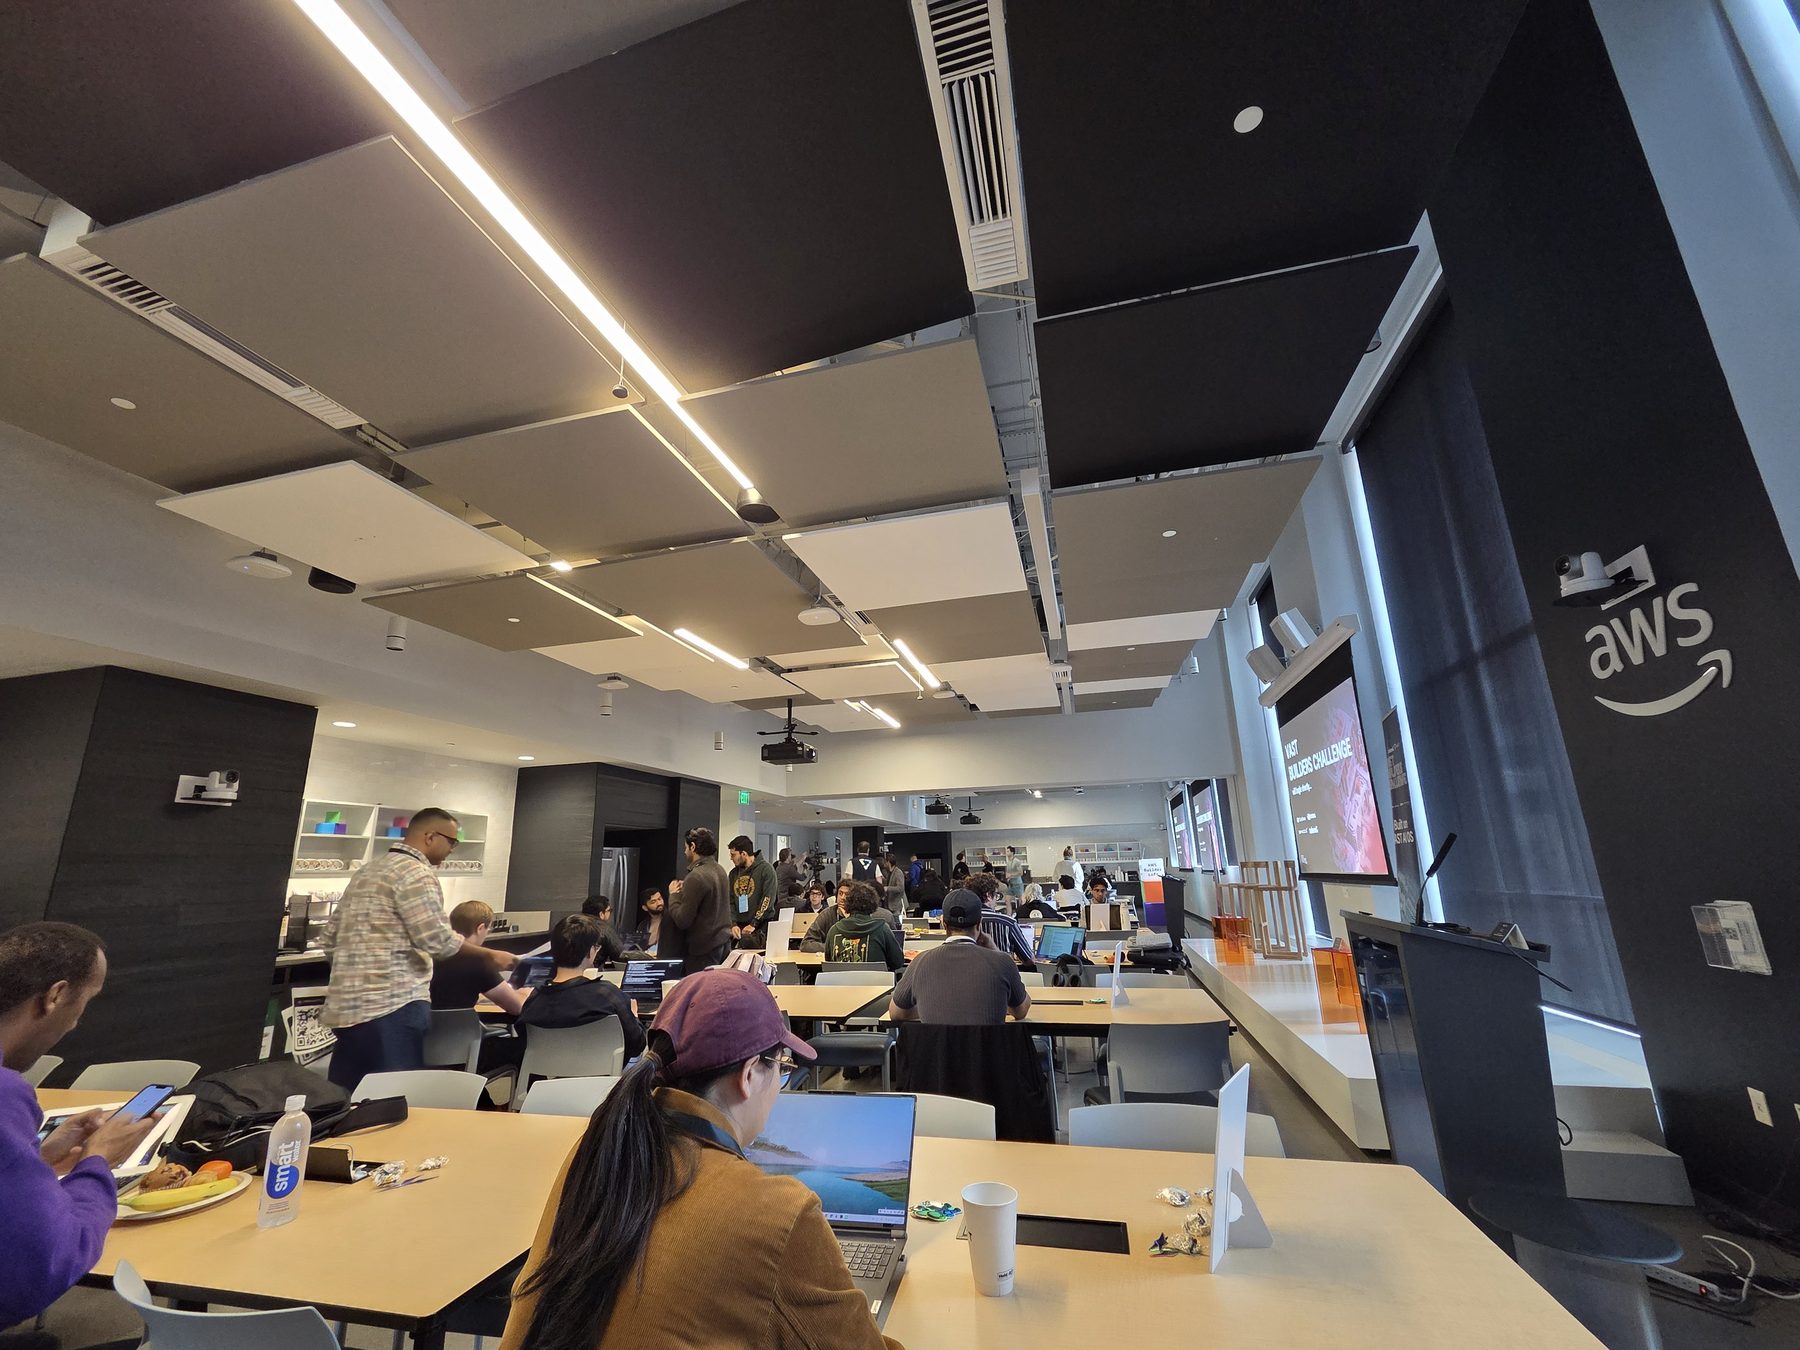
Vast sells a single VM with the GPU, the data, inference, a video model, and a coding environment stacked together. At the hackathon each team got a VM, with CoreWeave and Weights & Biases inference and Nvidia Cosmos Reason available.
Above that is the layer that picks a model and serves it. Inference companies at the OpenRouter event said that if you have GPUs, you can sell them all right now. A range of Higgsfield-like router companies…
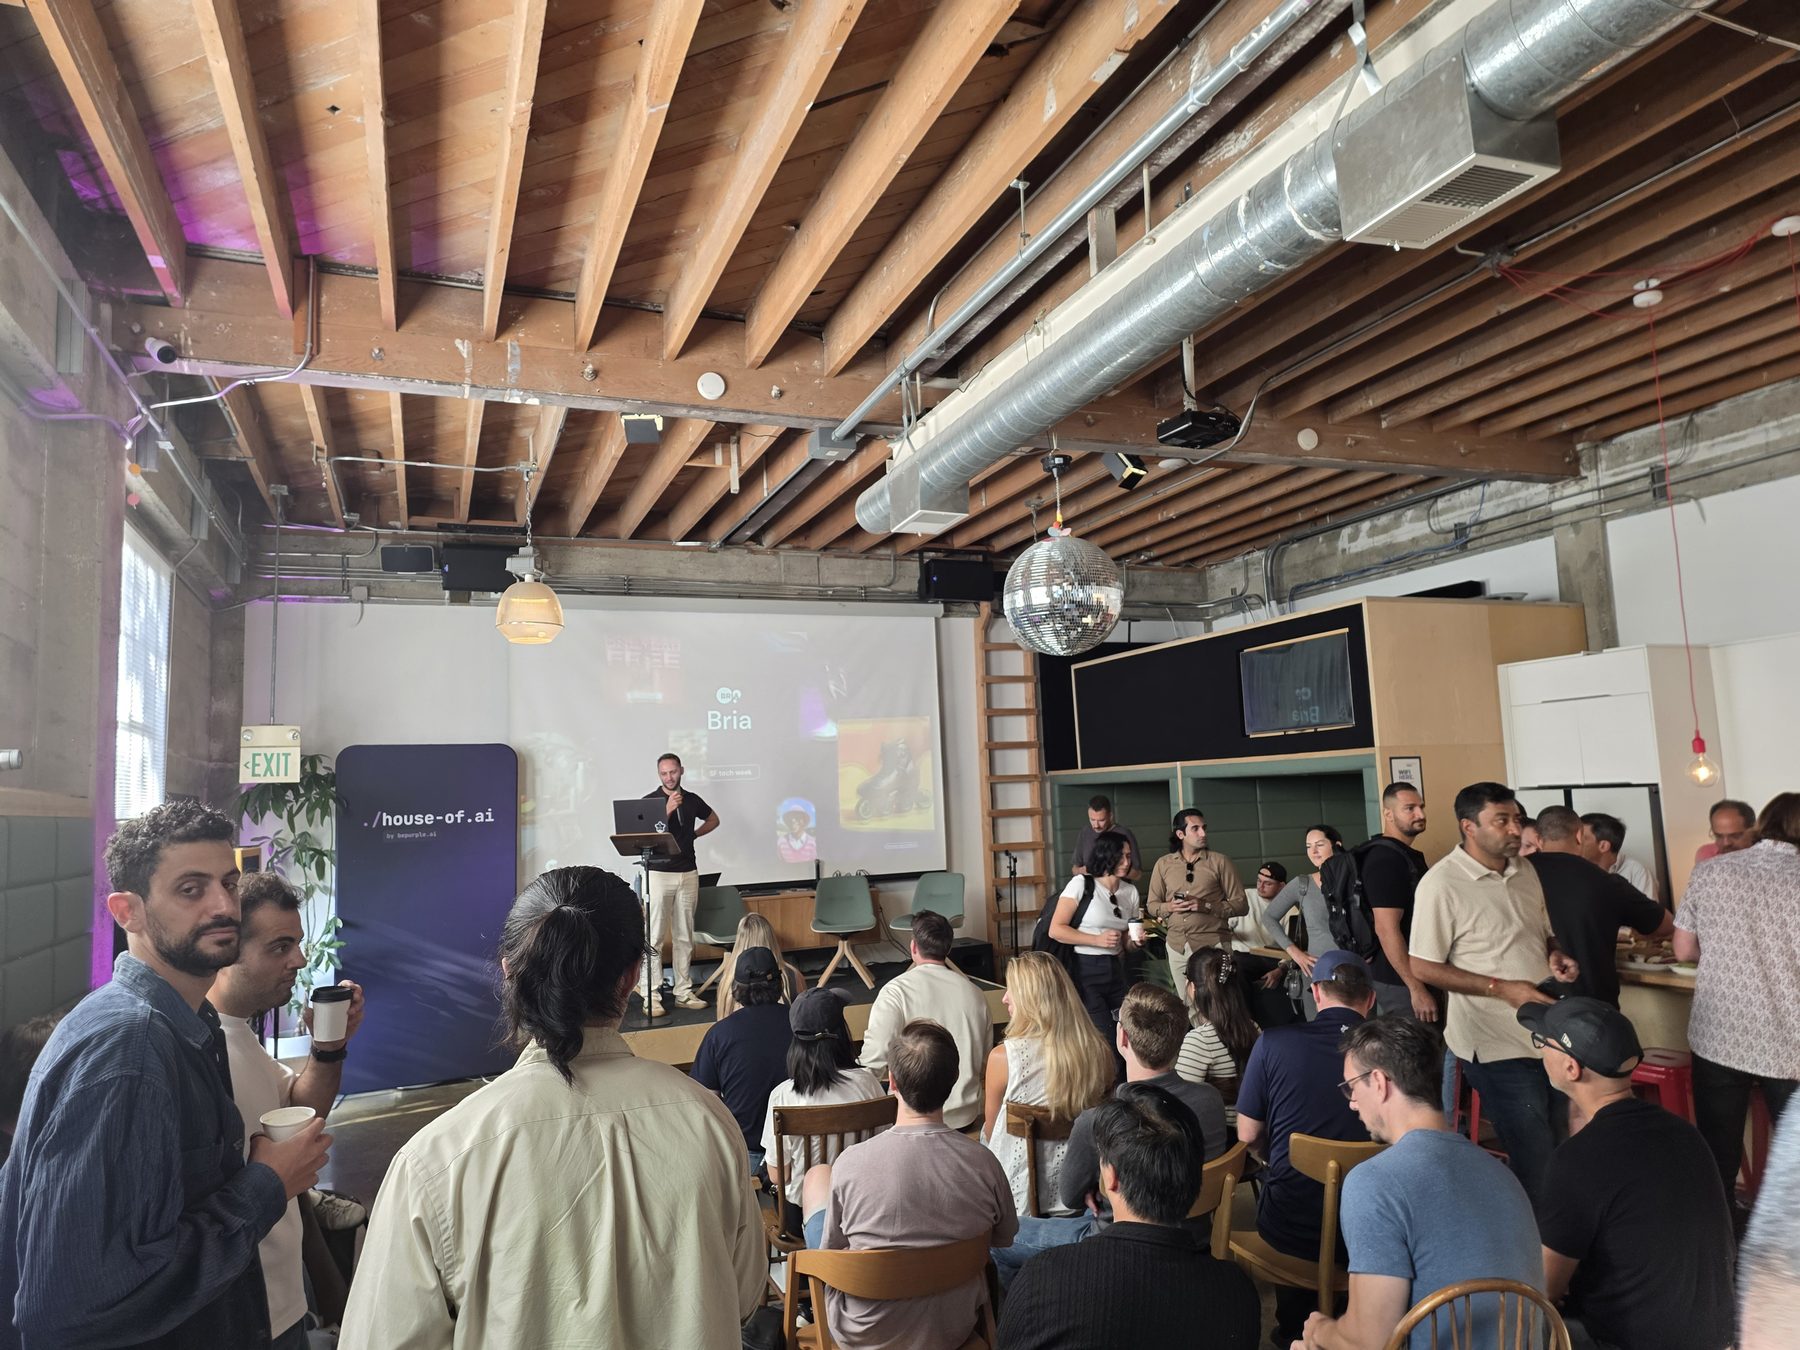
Fal, Bria, and LTX shared one event. Fal runs inference that adds music, dance, and effects.
Video generation
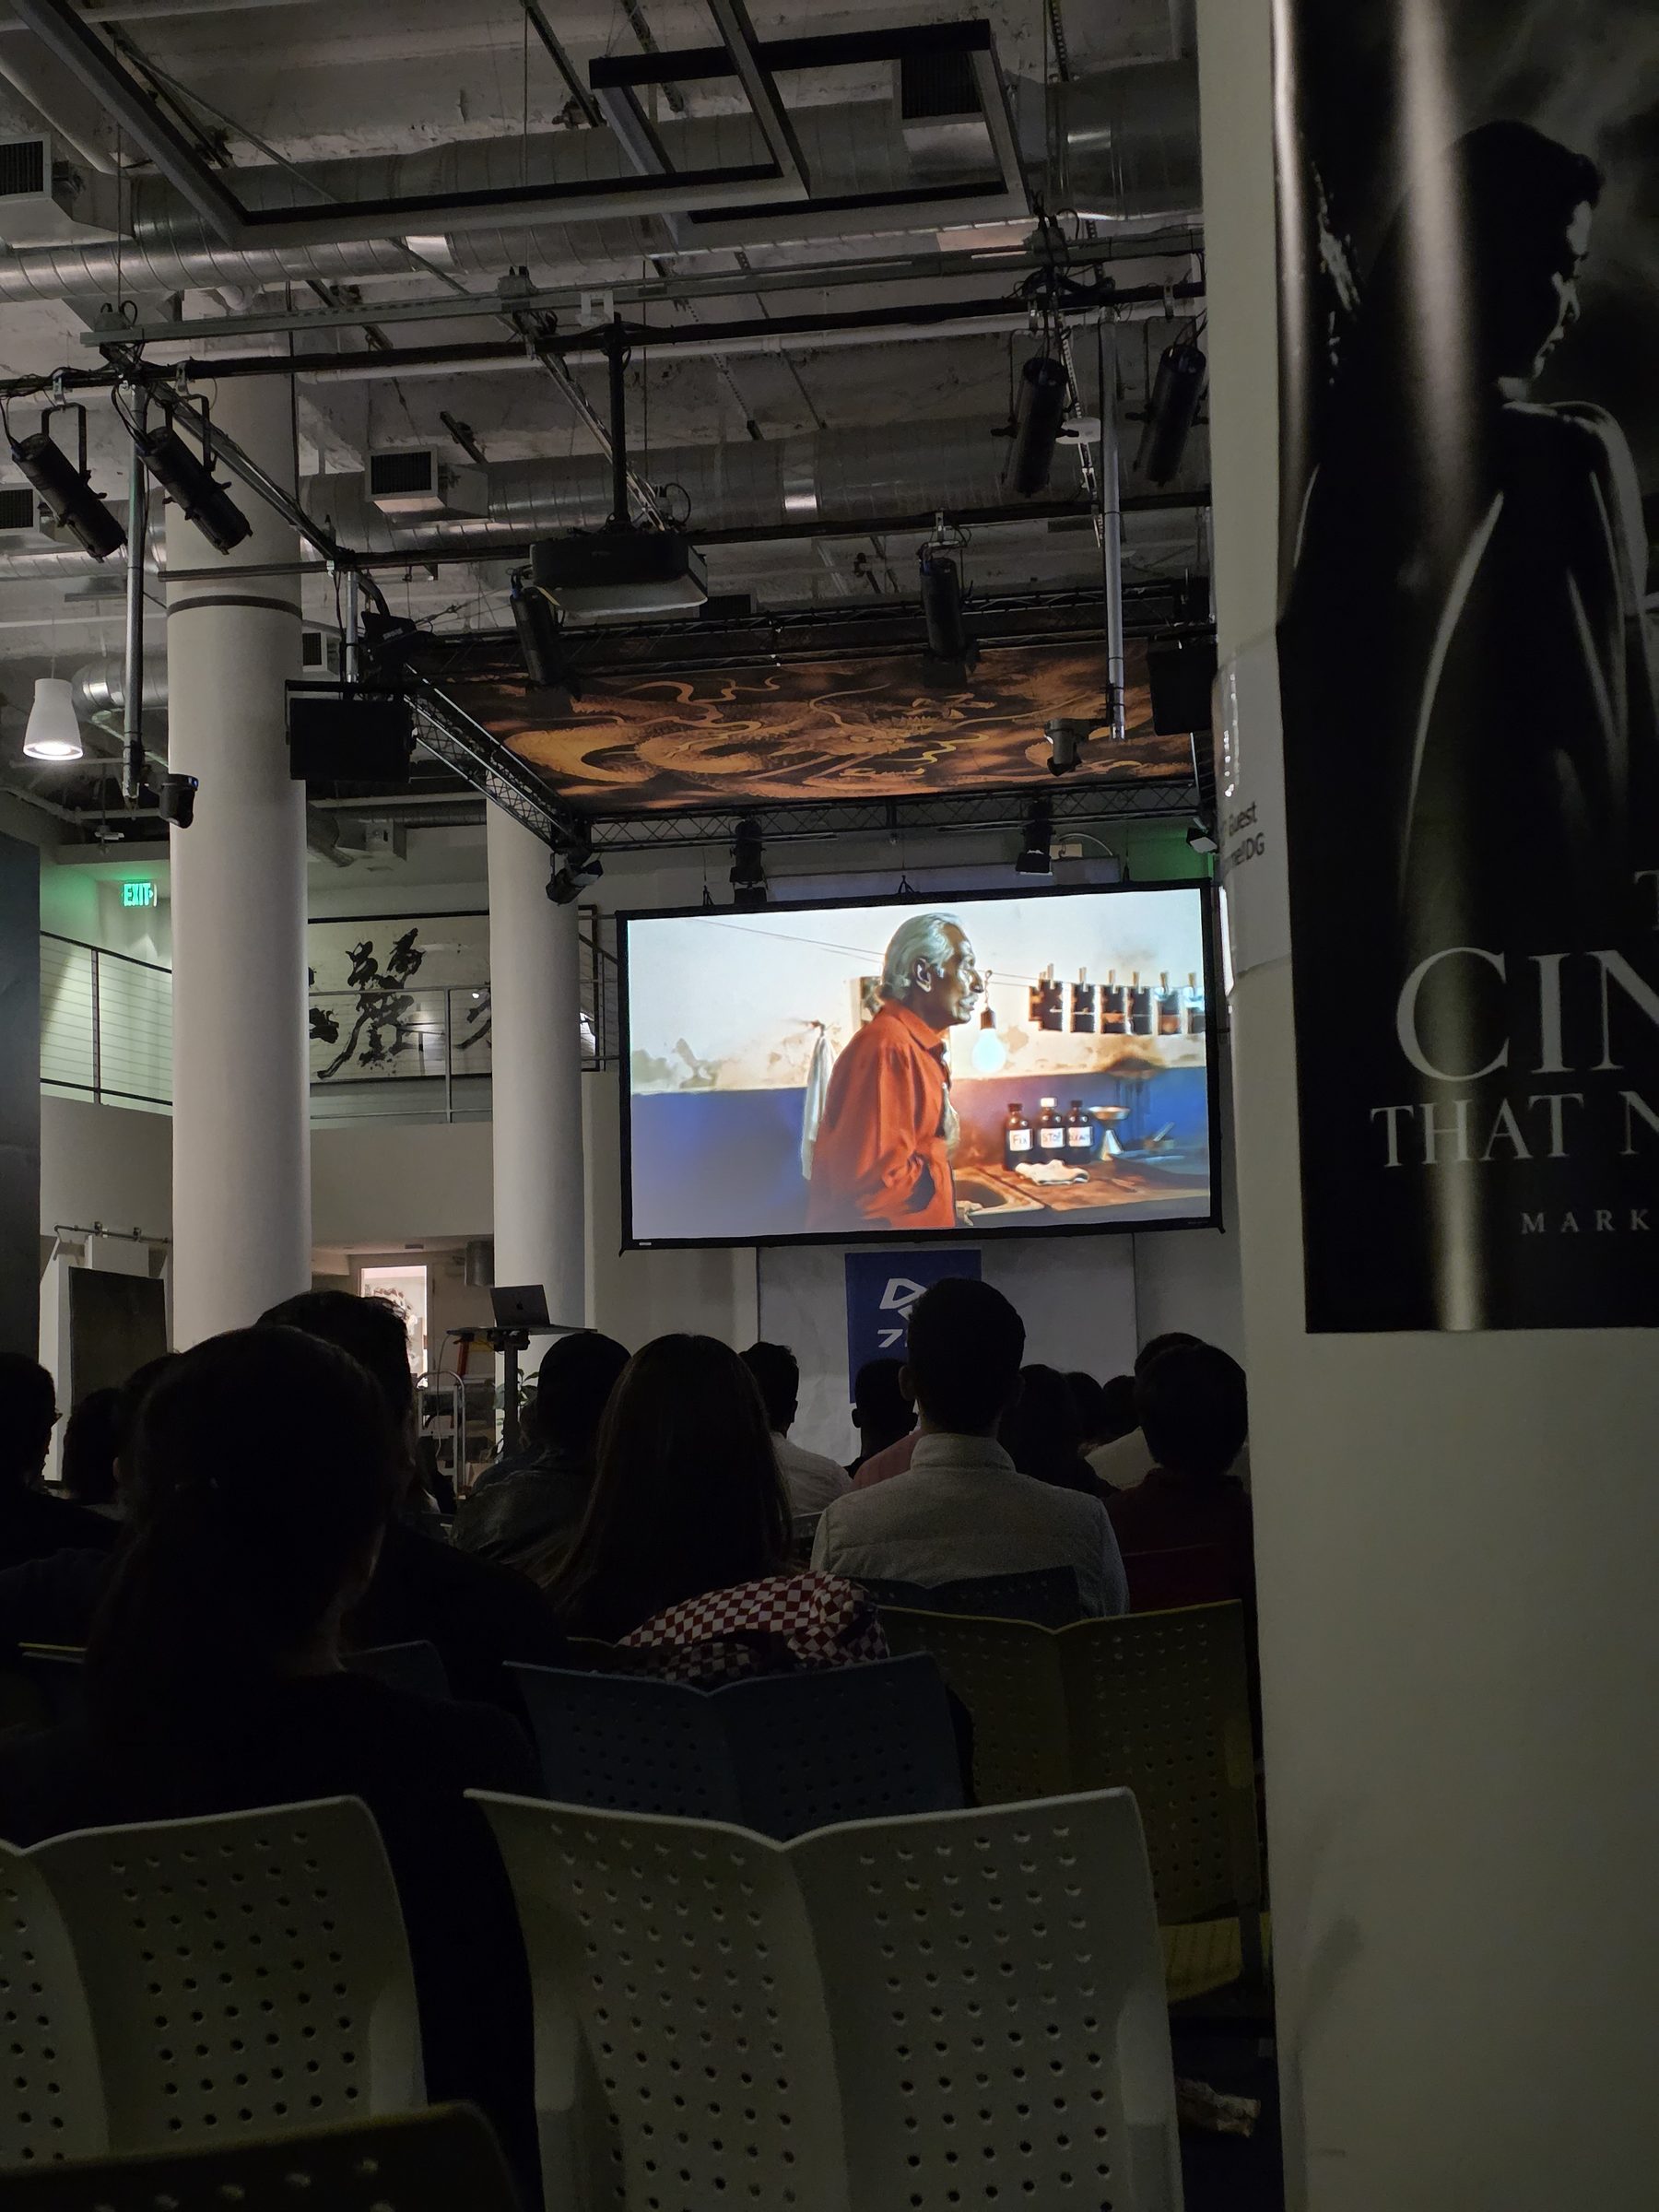
Dragon Gate was a screening of AI films. The people in the room were there for the films.
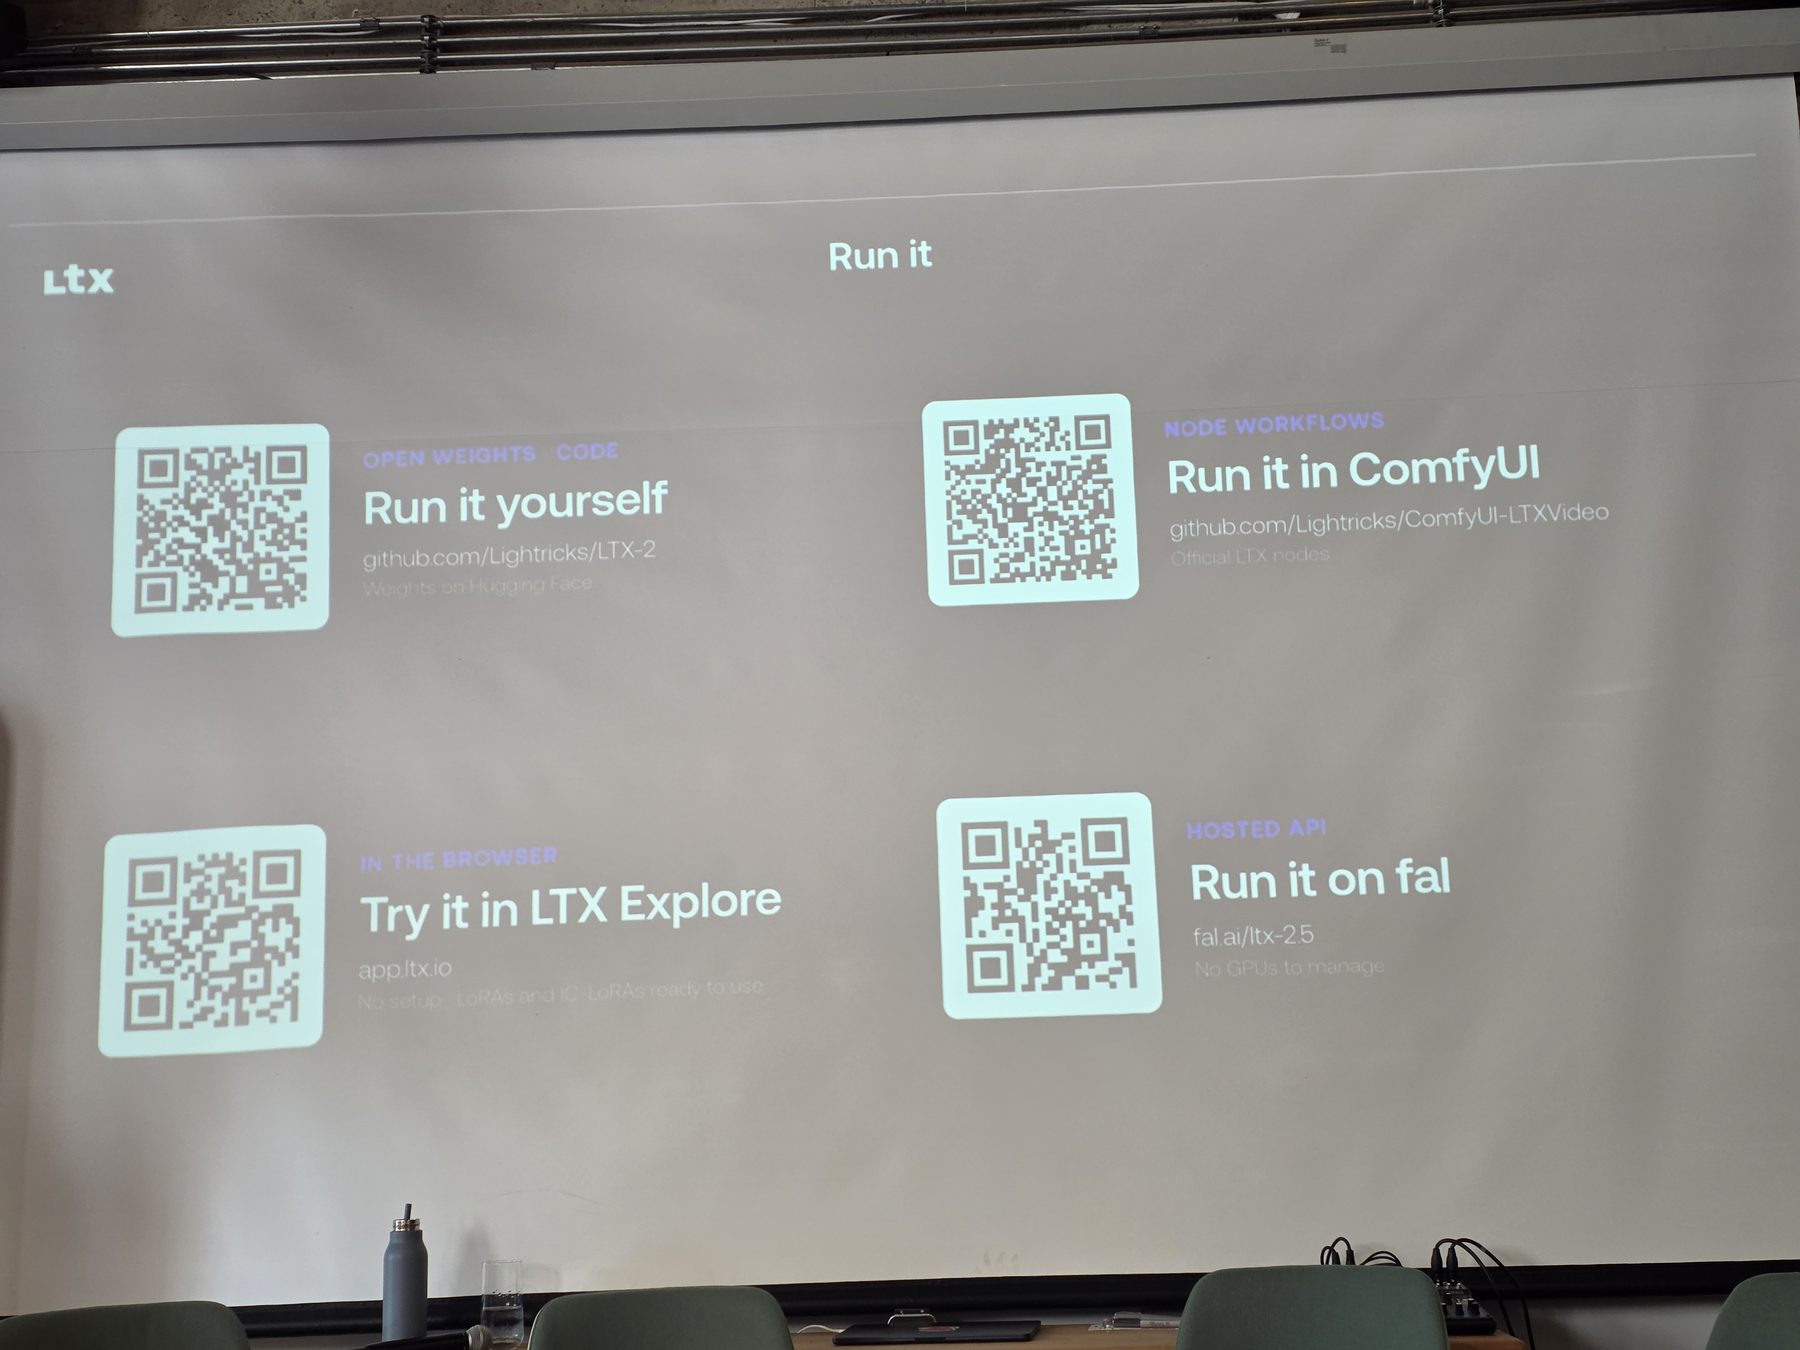
LTX tunes for film and animation production, down to outpainting, motion sync, and physical detail. If you only have a feeling, you say all of it out loud and let an LLM write the prompt. Serving is Fal.
Singapore-based AI is a film production platform, and the work they showed was at a high level. China’s short-form micro-dramas look like they are made this way. AI film studios already have several titles that have screened.
B2C niche models
At a Descript office event, staff stayed with people through filming and editing. At the same time they are building a forced aligner, FuseAlign, in-house. Facial expression and non-verbal audio are a later step. Audai builds audio models. Academa generates explainer videos automatically.
Robotics
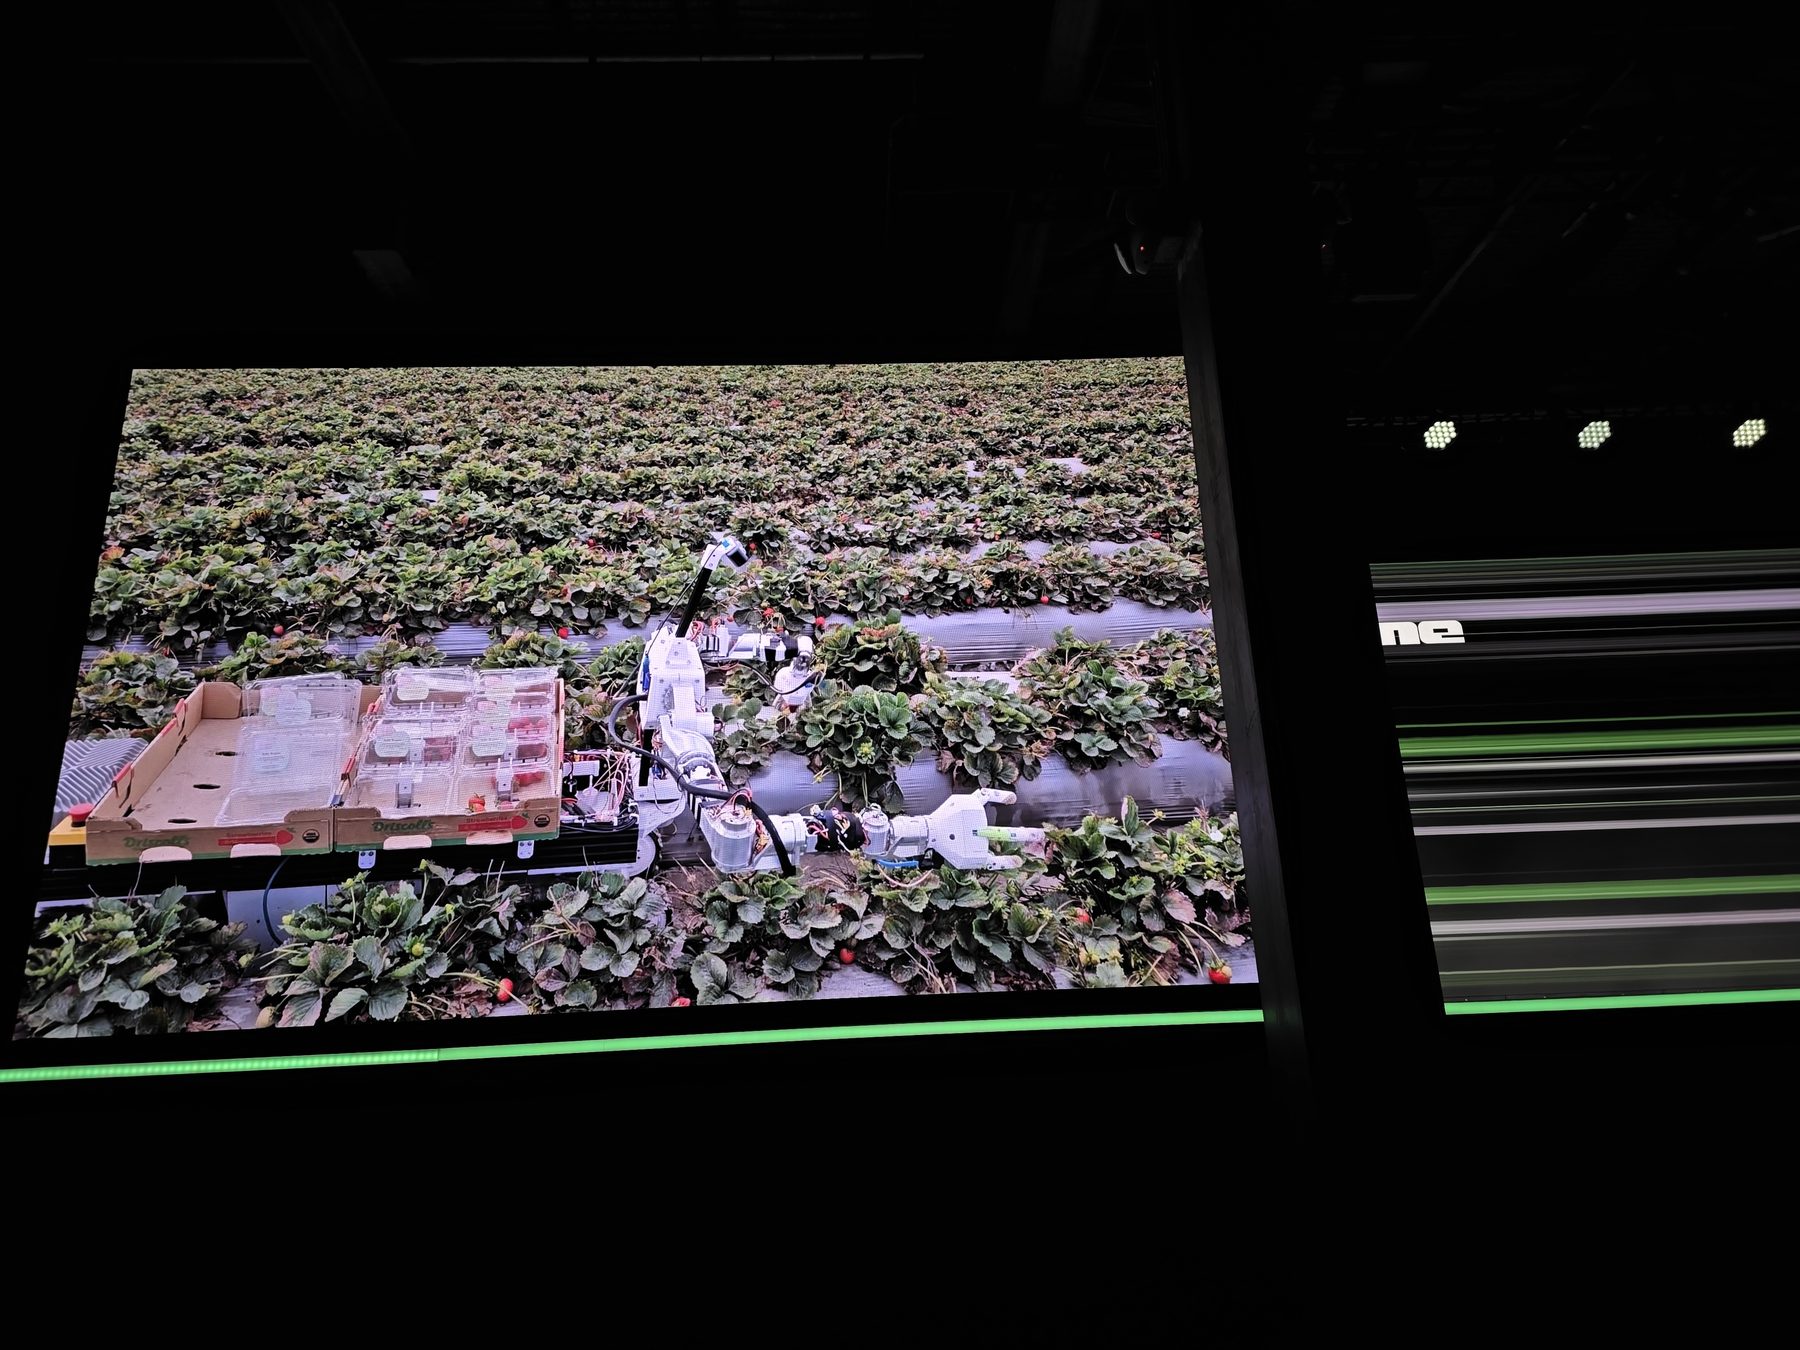
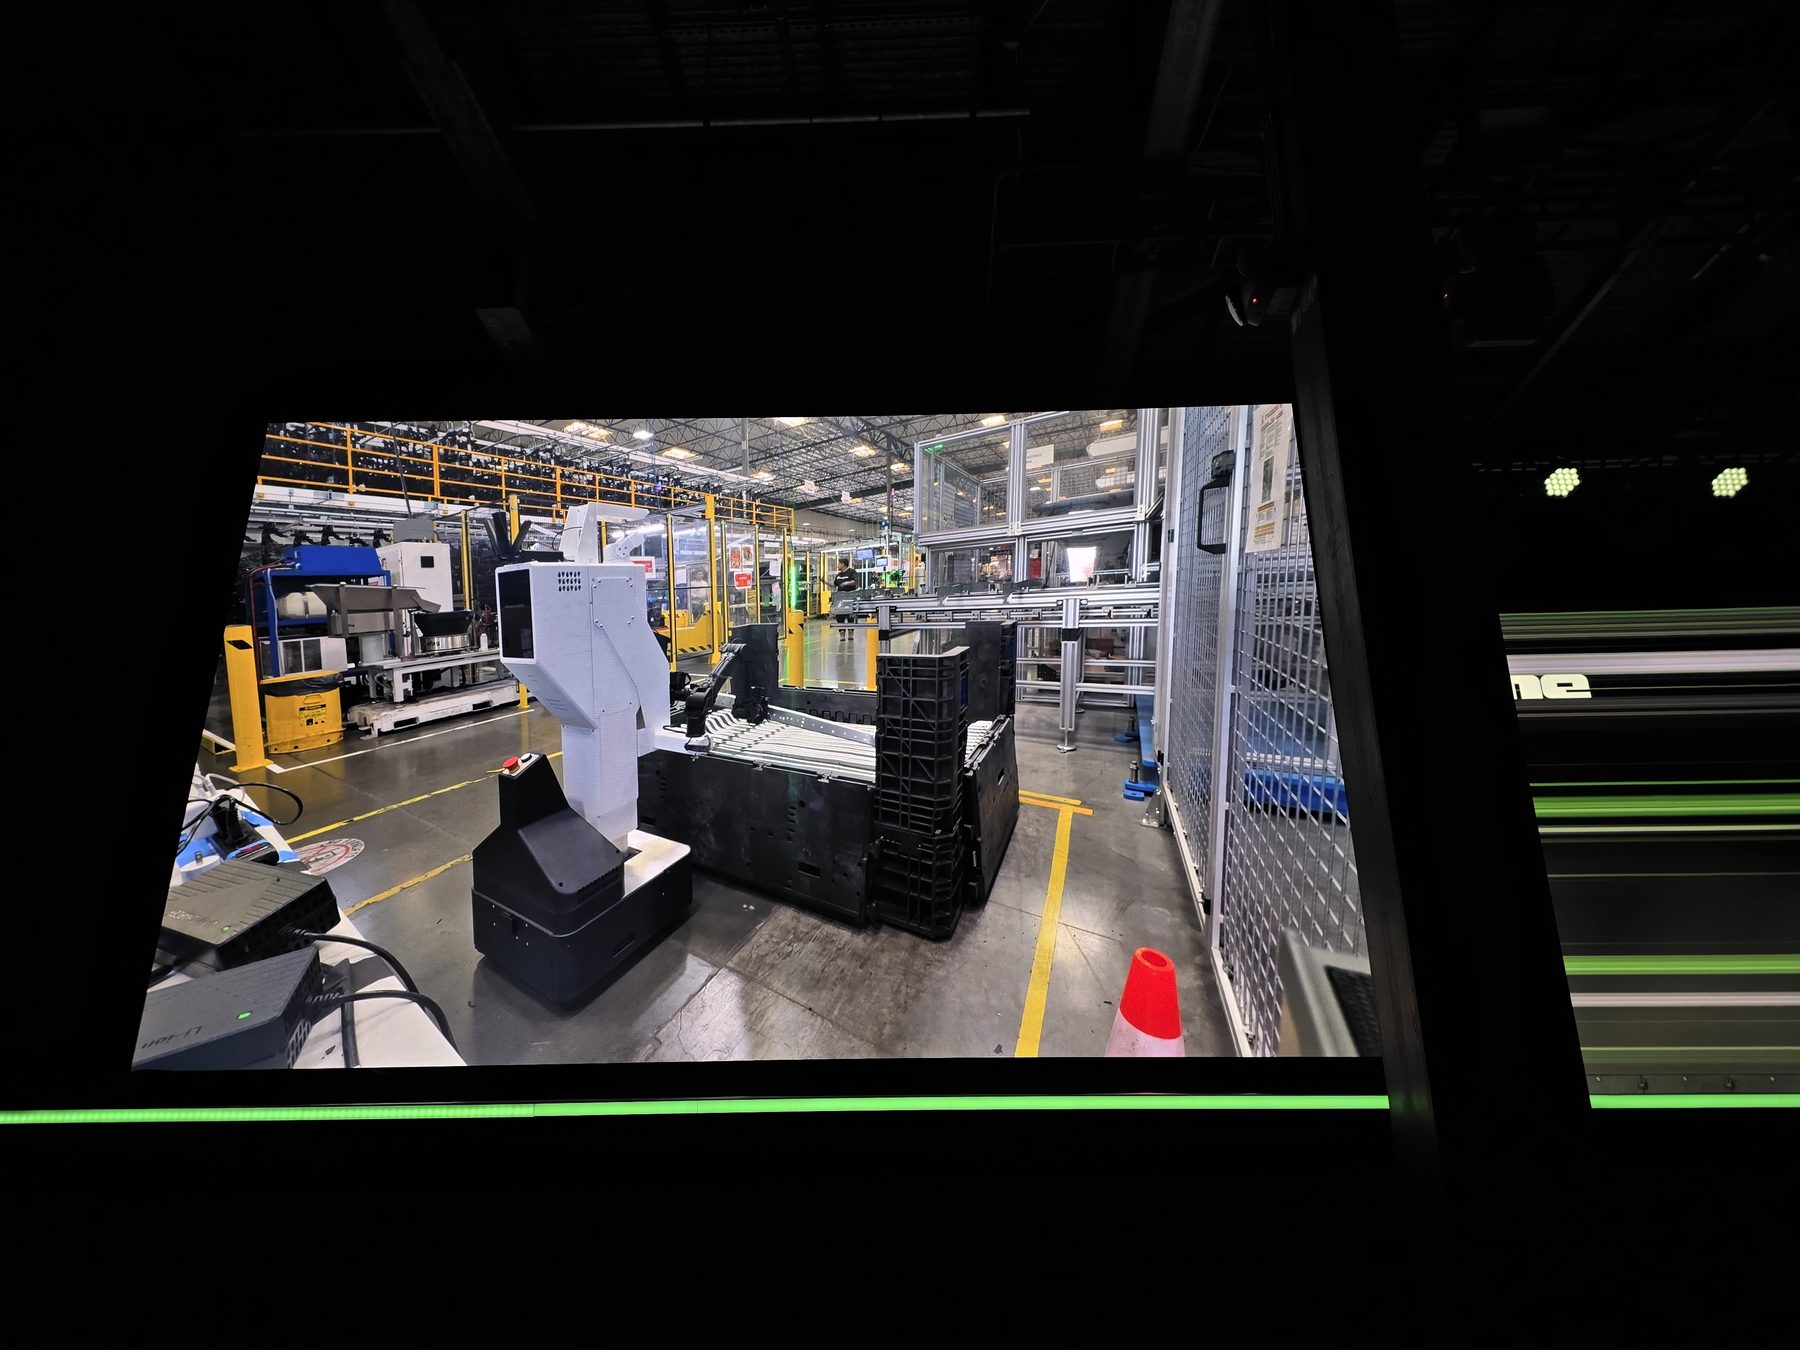
Generalist’s scaling still includes collecting data by uploading SD cards of footage. Physical Intelligence is in strawberry fields, cattle operations, excavators, and factories. 1X Neo was there in person. The walking was rough, and the gap between orders and delivery is still wide.
That is why Dreamscale is looking for local GPUs in SF. As more robots go into the field, inference that runs their brains inside the latency budget is its own problem.